

Dataset
SNLI
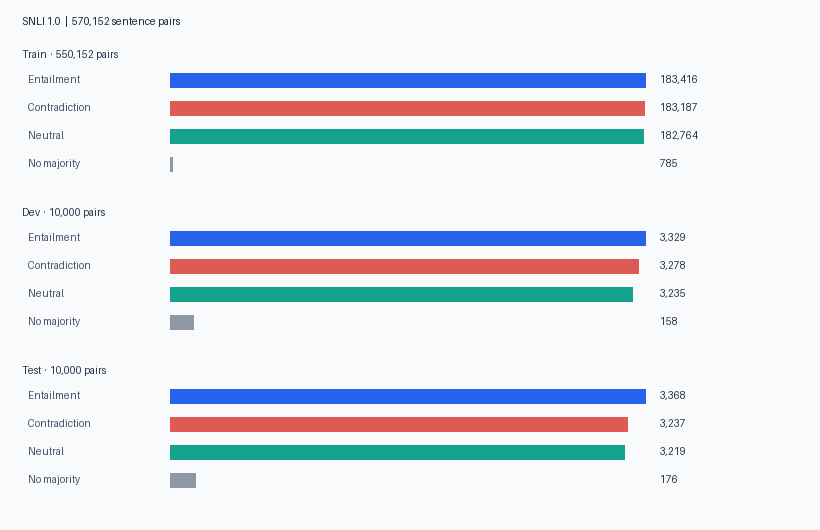
SNLI 1.0: 570,152 train/dev/test sentence pairs in a private ZIP with the official JSONL splits, source README, attribution and CC BY-SA 4.0 notice. Public preview shows aggregate labels only; the full sentence text is available after purchase.
570,152Records
47.2 MBFile size
ZIP / JSONLDelivery formats
Data sample
Field reference
The purchased version's schema snapshot is authoritative.Data quality
Quality metrics and processing details come from this version's acceptance report.dev_pairs10000
test_pairs10000
train_pairs550152
unlabeled_pairs1119
License
Stanford NLP SNLI 1.0 under CC BY-SA 4.0; source README includes Flickr30k/VisualGenome provenance and citation obligations.